 Member
 gregkh
My affidavit in the Geniatech vs. McHardy case
As many people know, last week there was a court hearing in the Geniatech vs. McHardy case. This was a case brought claiming a license violation of the Linux kernel in Geniatech devices in the German court of OLG Cologne.
Harald Welte has written up a wonderful summary of the hearing, I strongly recommend that everyone go read that first.
In Harald’s summary, he refers to an affidavit that I provided to the court. Because the case was withdrawn by McHardy, my affidavit was not entered into the public record. I had always assumed that my affidavit would be made public, and since I have had a number of people ask me about what it contained, I figured it was good to just publish it for everyone to be able to see it.
There are some minor edits from what was exactly submitted to the court such as the side-by-side German translation of the English text, and some reformatting around some footnotes in the text, because I don’t know how to do that directly here, and they really were not all that relevant for anyone who reads this blog. Exhibit A is also not reproduced as it’s just a huge list of all of the kernel releases in which I felt that were no evidence of any contribution by Patrick McHardy.
AFFIDAVIT

I, the undersigned, Greg Kroah-Hartman,
declare in lieu of an oath and in the
knowledge that a wrong declaration in
lieu of an oath is punishable, to be
submitted before the Court:

I. With regard to me personally:

1. I have been an active contributor to
   the Linux Kernel since 1999.

2. Since February 1, 2012 I have been a
   Linux Foundation Fellow.  I am currently
   one of five Linux Foundation Fellows
   devoted to full time maintenance and
   advancement of Linux. In particular, I am
   the current Linux stable Kernel maintainer
   and manage the stable Kernel releases. I
   am also the maintainer for a variety of
   different subsystems that include USB,
   staging, driver core, tty, and sysfs,
   among others.

3. I have been a member of the Linux
   Technical Advisory Board since 2005.

4. I have authored two books on Linux Kernel
   development including Linux Kernel in a
   Nutshell (2006) and Linux Device Drivers
   (co-authored Third Edition in 2009.)

5. I have been a contributing editor to Linux
   Journal from 2003 - 2006.

6. I am a co-author of every Linux Kernel
   Development Report. The first report was
   based on my Ottawa Linux Symposium keynote
   in 2006, and the report has been published
   every few years since then. I have been
   one of the co-author on all of them. This
   report includes a periodic in-depth
   analysis of who is currently contributing
   to Linux. Because of this work, I have an
   in-depth knowledge of the various records
   of contributions that have been maintained
   over the course of the Linux Kernel
   project.

   For many years, Linus Torvalds compiled a
   list of contributors to the Linux kernel
   with each release. There are also usenet
   and email records of contributions made
   prior to 2005. In April of 2005, Linus
   Torvalds created a program now known as
   “Git” which is a version control system
   for tracking changes in computer files and
   coordinating work on those files among
   multiple people. Every Git directory on
   every computer contains an accurate
   repository with complete history and full
   version tracking abilities.  Every Git
   directory captures the identity of
   contributors.  Development of the Linux
   kernel has been tracked and managed using
   Git since April of 2005.

   One of the findings in the report is that
   since the 2.6.11 release in 2005, a total
   of 15,637 developers have contributed to
   the Linux Kernel.

7. I have been an advisor on the Cregit
   project and compared its results to other
   methods that have been used to identify
   contributors and contributions to the
   Linux Kernel, such as a tool known as “git
   blame” that is used by developers to
   identify contributions to a git repository
   such as the repositories used by the Linux
   Kernel project.

8. I have been shown documents related to
   court actions by Patrick McHardy to
   enforce copyright claims regarding the
   Linux Kernel. I have heard many people
   familiar with the court actions discuss
   the cases and the threats of injunction
   McHardy leverages to obtain financial
   settlements. I have not otherwise been
   involved in any of the previous court
   actions.

II. With regard to the facts:

1. The Linux Kernel project started in 1991
   with a release of code authored entirely
   by Linus Torvalds (who is also currently a
   Linux Foundation Fellow).  Since that time
   there have been a variety of ways in which
   contributions and contributors to the
   Linux Kernel have been tracked and
   identified. I am familiar with these
   records.

2. The first record of any contribution
   explicitly attributed to Patrick McHardy
   to the Linux kernel is April 23, 2002.
   McHardy’s last contribution to the Linux
   Kernel was made on November 24, 2015.

3. The Linux Kernel 2.5.12 was released by
   Linus Torvalds on April 30, 2002.

4. After review of the relevant records, I
   conclude that there is no evidence in the
   records that the Kernel community relies
   upon to identify contributions and
   contributors that Patrick McHardy made any
   code contributions to versions of the
   Linux Kernel earlier than 2.4.18 and
   2.5.12. Attached as Exhibit A is a list of
   Kernel releases which have no evidence in
   the relevant records of any contribution
   by Patrick McHardy.
Affidavit
As many people know, last week there was a court hearing in the Geniatech vs. McHardy case. This was a case brought claiming a license violation of the Linux kernel in Geniatech devices in the German court of OLG Cologne.
Harald Welte has written up a wonderful summary of the hearing, I strongly recommend that everyone go read that first.
In Harald’s summary, he refers to an affidavit that I provided to the court. Because the case was withdrawn by McHardy, my affidavit was not entered into the public record. I had always assumed that my affidavit would be made public, and since I have had a number of people ask me about what it contained, I figured it was good to just publish it for everyone to be able to see it.

2018w09-10: ReviewBot comment commands, quality of life changes, metrics.o.o for Grafana 5.x and TW release data, and more
ReviewBot overrides via comment commands
Something which has been discussed for quite a while, a method for overriding bot reviews, was added recently. The functionality ended up being to interpret comments in the form @bot <command> [args...]. Comment commands are then restricted to members of either a configured group or the staging group. For example release overrides addressed to leaper may be issued by anyone in leap-reviewers group or factory-staging (responsible for staging process).
repo-checker gained the ability to skip the cycles check via a comment command placed on a staging project (@repo-checker skip-cycle). Previously, this had to be done via the command line by manually running the bot.
The final decision towards this workflow was clear after it turned out OBS groups were insufficient for the override workflow.
leaper was also modified to leave previously declined reviews open for SLE manager override. A similar change will be made to the openSUSE portion of the bot.
Quality of life changes
Instead of printing the list of packages, requiring the package to be deleted, to build as a flat list it is formatted as a bulleted list by repo-checker.
sad-package is still a build requirement of package1, package2, package3
to
sad-package is still a build requirement of:

- package1
- package2
- package3
Similarly, ReviewBots were changed to accept unhandled request types without posting a comment to reduce e-mail spam.
All config options are now lazy-loaded to allow for placement in remote config.
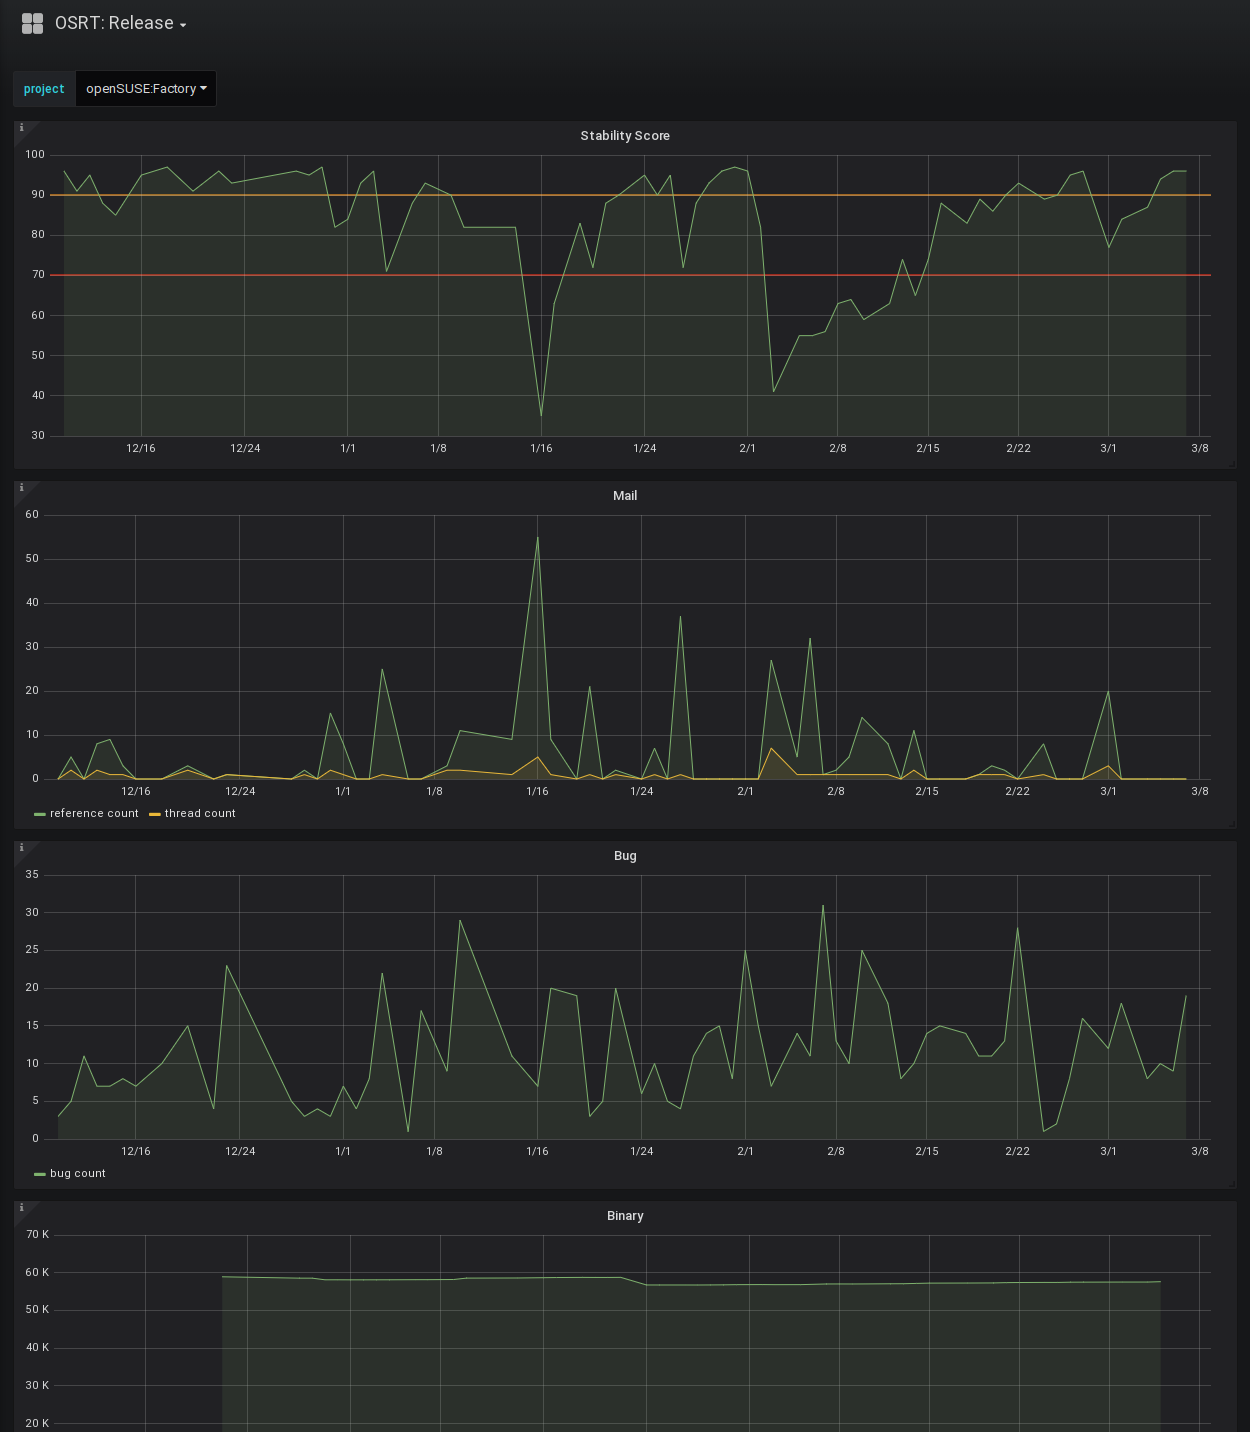
metrics.o.o update for Grafana 5.x and TW review site
In light of the Grafana 5.x series changing the dashboard format the existing 4.x dashboards were migrated. The Tumbleweed snapshot review site data can now also be ingested and presented. Both improvements are scheduled for deployment to metrics.opensuse.org next week.
pkglistgen adventures
A rather interesting bug was causing the pkglistgen.py code to crash on Leap 15.0 after Build153.1 during drop list creation. It ended up being solved by adding a flush() call before passing the file to read by libsolv. The situation would have been easier to resolve if the libsolv components complained about in incomplete XML file, but instead the invalid data makes it through a chain of tools before being read by a tool that complains. In addition to fixing the problem the metadata hash is now validated as further assurance that the correct data is present.
The repo metadata hash for update repos is now used to avoid downloading unchanged information.
To complete the week for pkglistgen the addition of services to Leap 15.0 exposed the need to skip local service run during update.
repo-checker for SLE 15
Lastly, the repo-checker is now utilized for SLE 15.0 development which should reduce both the pre-release problems in SLE 15, but also in Leap 15.0 since it sources core packages from SLE. In combination with Factory this should elevate the quality of pre-releases and even the final releases in addition to reducing negative staging results.
last year
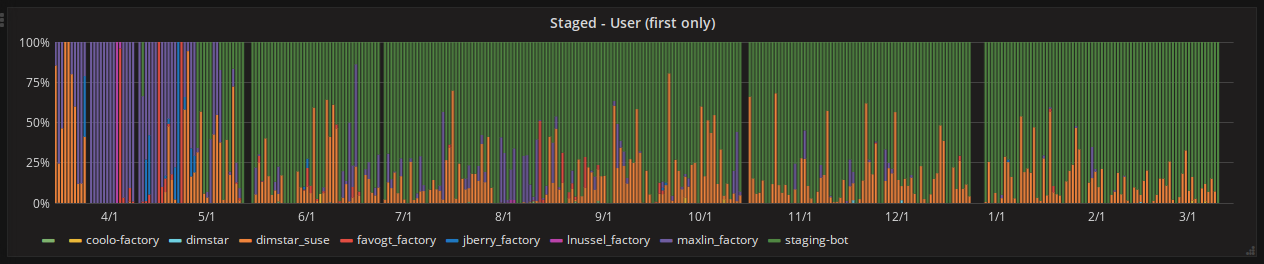
One of the biggest acheivements of last year was the introduction of select automation: merge and strategies which ended up taking over the majority of staging grouping work. An example of using the strategies in interactive mode can be seen in 2018w01-02. The work was based on observations and involvement with Leap 42.3 and Factory staging. Five strategies were created which are evaluated against the open requests based on a priority order. The result is rather powerful automated staging and follow-up staging.
Stagings which were initially filled using a strategy can have further requests --merged into them that match the same strategy. This combined with configurable time period since first staging and other conditions makes for a solid follow-up workflow allowing maintainers to send requests organically. An initial waiting period of an hour is used to allow for patterns to emerge.
A staging-bot user was created under which this code and more now runs as a service. One can clearly see it take over for Factory in the Staged - User* graphs on metrics.opensuse.org.
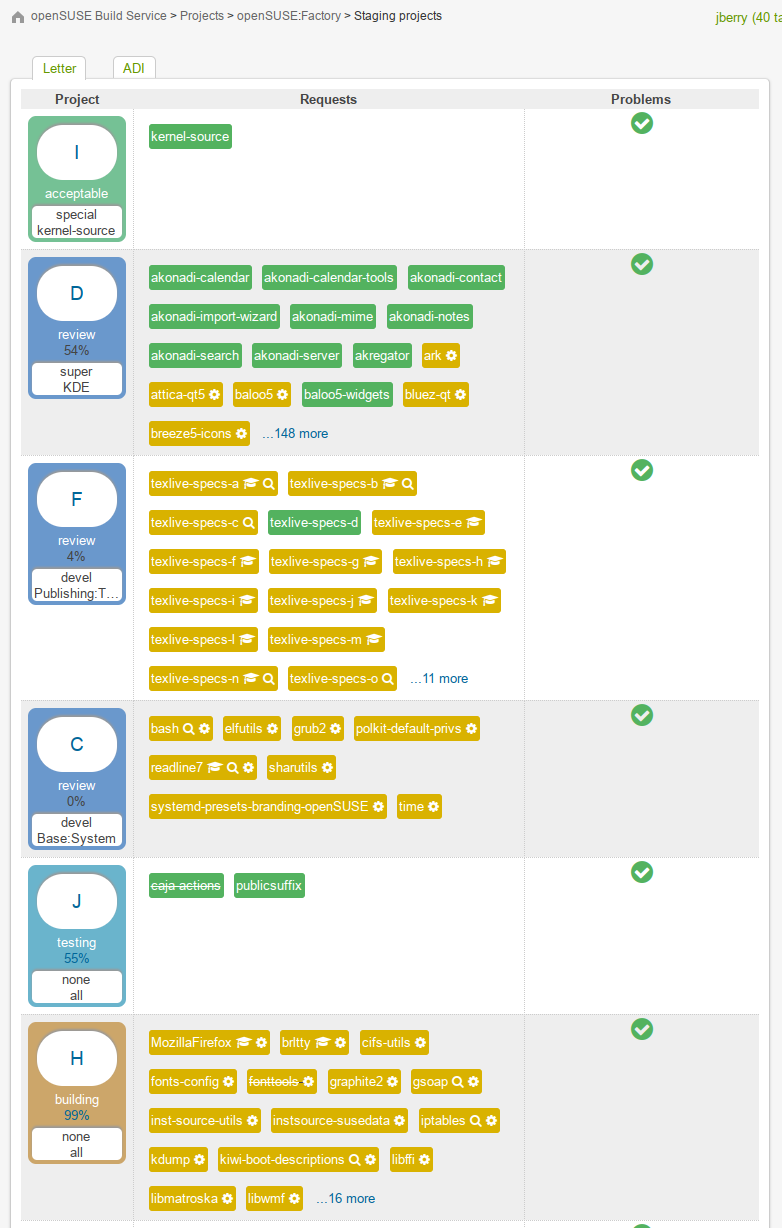
The strategies were also integrated into the OBS dashboard which allows one to quickly tell what strategy was used for each staging. Note the white section within the Project column on the left in the below images (ex. special, kernel-source).
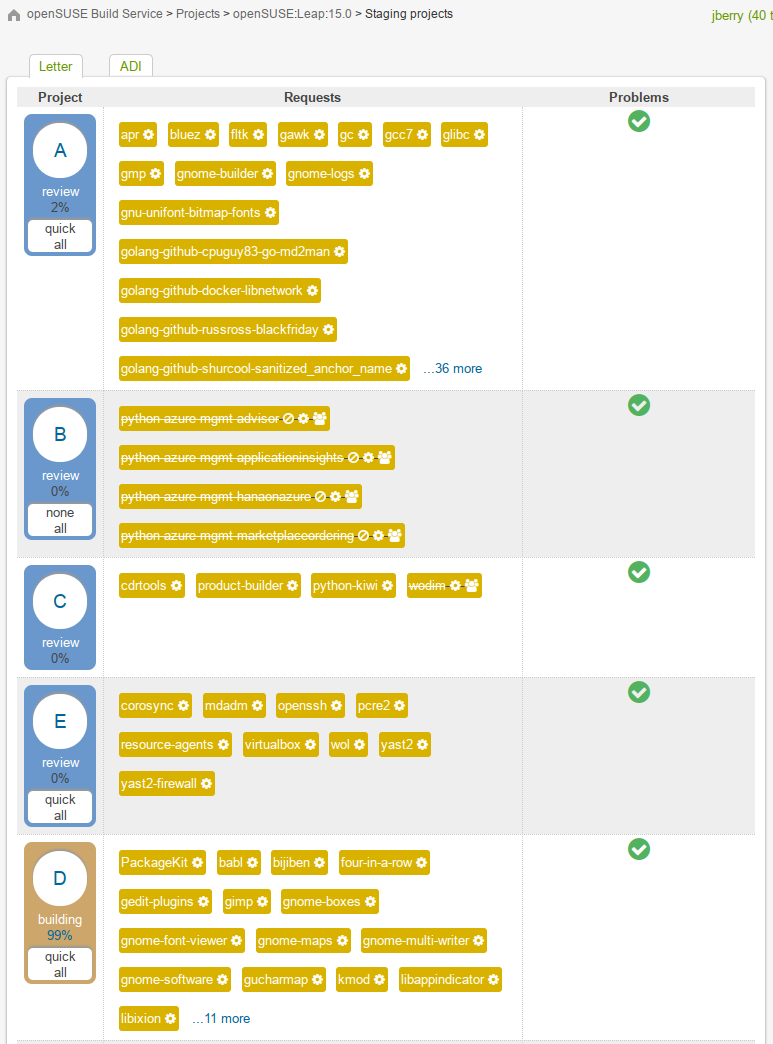
The existing feature set was documented in repo wiki for staging masters and future plans were organized in a github project.
Towards the same goal of automating staging work several commands were given --cleanup flags to remove mundane and neglected tasks. Similarly, a rebuild command was introduced to trigger rebuilds of flaky packages rather than waiting hours for a staging master to come around.
A couple quality of life improvements were made:
-
frozenagedefaults to all letter stagings (to avoid typing all of them) -
include a
--messageoption inunselectto allow for ignoring a request while un-staging since both are commonly done together -
provide an
unlockcommand to resolve stuck staging locks
All in the same week, a tool for interacting with devel projects was introduced. The tool provides an overview of the requests to devel projects and the open reviews for devel project (requests targeting Factory). The --remind feature is run as a service to create review reminder comments of which contributors are likely familiar.
On the OBS end, changes were made to the obs_factory plugin in order to improve development experience, harden validation, and enhance the API for use by the staging tools. Rather than make hundreds of individual API calls a single aggregate call could be made which drastically improved performance.
What 3 Words?
I dig online maps like everyone else, but it is somewhat clumsy sharing a location. The W3W service addesses the issue by chunking up the whole world into 3x3m squares and assigning each a name (Supposedly around 57 trillion). Sometimes it’s a bit of a tongue twister, but most of the time it’s fun to say to meet at a “massive message chuckle” for some fpv flying. I’m really surprised this didn’t take off.
Cephalocon APAC ... is comming
 Two weeks till Cephalocon APAC 2018 in Beijing (22-23th March), the first Ceph-only conference. Finally! Two full days of talks and speaker from the world wide Ceph Community. The agenda is available since a few days now.

Helping Cairo
Cairo needs help. It is the main 2D rendering library we use in GNOME, and in particular, it's what librsvg uses to render all SVGs.
My immediate problem with Cairo is that it explodes when called with floating-point coordinates that fall outside the range that its internal fixed-point numbers can represent. There is no validation of incoming data, so the polygon intersector ends up with data that makes no sense, and it crashes.
I've been studying how Cairo converts from floating-point to its
fixed-point representation, and it's a nifty little algorithm. So I
thought, no problem, I'll add validation, see how to represent the
error state internally in Cairo, and see if clients are happy with
getting back a cairo_t in an error state.
Cairo has a very thorough test suite... that doesn't pass. It is documented to be very hard to pass fully for all rendering backends. This is understandable, as there may be bugs in X servers or OpenGL implementations and such. But for the basic, software-only, in-memory image backend, Cairo should 100% pass its test suite all the time. This is not the case right now; in my tree, for all the tests of the image backend I get
497 Passed, 54 Failed [0 crashed, 14 expected], 27 Skipped
I have been looking at test failures to see what needs fixing. Some reference images just need to be regenerated: there have been minor changes in font rendering that broke the reference tests. Some others have small differences in rendering gradients - not noticeable by eye, just by diff tools.
But some tests, I have no idea what changed that made them break.
Cairo's git repository is accessible through [cgit.freedesktop.org]. As far as I know there is no continuous integration infrastructure to ensure that tests keep passing.
Adding minimal continuous testing
I've set up a Cairo repository at gitlab.com. That branch
already has a fix for an uninitialized-memory bug which leads to an
invalid free(), and some regenerated test files.
The repository is configured to run a continuous integration pipeline on every commit. The test artifacts can then be downloaded when the test suite fails. Right now it is only testing the image backend, for in-memory software rendering.
Initial bugs
I've started reporting a few bugs against that repository for tests that fail. These should really be in Cairo's Bugzilla, but for now Gitlab makes it much easier to include test images directly in the bug descriptions, so that they are easier to browse. Read on.
Would you like to help?
A lot of projects use Cairo. We owe it to ourselves to have a library with a test suite that doesn't break. Getting to that point requires several things:
- Fixing current failures in the image backend.
- Setting up the CI infrastructure to be able to test other backends.
- Fixing failures in the other backends.
If you have experience with Cairo, please take a look at the bugs. You can see the CI configuration to see how to run the test suite in the same fashion on your machine.
I think we can make use of modern infrastructure like gitlab and continuous integration to improve Cairo quickly. Currently it suffers from lack of attention and hostile tools. Help us out if you can!
ECMAScript 2018: Asynchronous Iteration

It’s 2018 and it’s time for an update to the JavaScript standard. In January this year the TC39 committee released the latest changes to the ECMAScript standard, appropriately called ECMAScript 2018. One of the changes coming in this update is the introduction of Asynchronous Iteration and the for-await-of loop to iterate over asynchronous functions like generators and promises.
Synchronous Iteration
The form of iteration JS programmers are used to using is called Synchronous Iteration. It is used to iterate over things like an array or a function that has completes execution and returns a result.
It is possible for you to implement your own custom iterators for objects you create. The link above has an in depth explanation of how these iterators work and the different ways they can be used. I will summarize their usage like so:
- Synchronous iteration requires the target object to be iterable
- An object is iterable if it defines [Symbol.iterator]()
- [Symbol.iterator]() must return an iterator
- An iterator is an object that must at least define a function next()
- The function next() must return an object in the form {value: $value, done: false} when iterating over values
- The iterator is considered finished when the next() function returns {done: true}
Here is an example implementation of a custom iterable:
The problem with these synchronous iterators is that they can not be used to iterate over asynchronous operations, like calling a generator function (since generator functions call yield, they do not “finish” executing). To solve this problem the TC39 committee has added asynchronous iteration to the ECMAScript 2018 release.
Asynchronous Iteration
ES2018: asynchronous iteration
The new form of iteration, to use when iterating over asynchronous iterators is called asynchronous iteration. It is similar to its synchronous counterpart but instead of defining [Symbol.iterator]() the iterable must instead define [Symbol.asyncIterator](). The creation of asynchronous iterators is as follows:
- Asynchronous iteration requires the target object to be iterable
- An object is iterable if it defines [Symbol.asyncIterator]()
- [Symbol.asyncIterator]() must return an AsyncIterator
- An AsyncIterator is an object that must at least define a function next()
- The function next() must return a promise that resolves with an IteratorResult
- The IteratorResult is an object with a form {value: $value, done: false}
- When the iterator is finished it must return {done: true}
However unlike the synchronous iterators, the asynchronous iterators cannot be used in a standard for-of loop. Instead they must use the new for-await-of loop. I have created an implementation of the synchronous iterator example above using asynchronous iterators below. Notice how the next() function in the iterable return a Promise instead of an object like in the first example. Also worth noting is that we have to use an asynchronous function to await for the result of the asynchronous iteration before we can update the page.
While the example is clearly more involved than the first, hopefully you can see that the asynchronous iterators now give developers the power to iterate over Promises and generator functions.
ECMAScript 2018: Asynchronous Iteration was originally published in Information & Technology on Medium, where people are continuing the conversation by highlighting and responding to this story.
Representing the Impractical and Impossible with JDK 10 “var”
Having benefited from “var” for many years when writing c#, I’m delighted that Java is at last getting support for local variable type inference in JDK 10.
From JDK 10 instead of saying
ArrayList<String> foo = new ArrayList<String>();
we can say
var foo = new ArrayList<String>();
and the type of “foo” is inferred as ArrayList<String>
While this is nice in that it removes repetition and reduces boilerplate slightly, the real benefits come from the ability to have variables with types that are impractical or impossible to represent.
Impractical Types
When transforming data it’s easy to be left with intermediary representations of the data that have deeply nested generic types.
Let’s steal an example from a c# linq query, that groups a customer’s orders by year and then by month.
While Java doesn’t have LINQ, we can get fairly close thanks to lambdas.
from(customerList)
    .select(c -> tuple(
        c.companyName(),
        from(c.orders())
            .groupBy(o -> o.orderDate().year())
            .select(into((year, orders) -> tuple(
                year,
                from(orders)
                    .groupBy(o -> o.orderDate().month())
            )))
       ));
While not quite as clean as the c# version, it’s relatively similar. But what happens when we try to assign our customer order groupings to a local variable?
CollectionLinq<Tuple<String, CollectionLinq<Tuple<Integer, Group<Integer, Order>>>>> customerOrderGroups =
   from(customerList)
   .select(c -> tuple(
       c.companyName(),
       from(c.orders())
           .groupBy(o -> o.orderDate().year())
           .select(into((year, orders) -> tuple(
               year,
               from(orders)
                   .groupBy(o -> o.orderDate().month())
           )))
   ));
Oh dear, that type description is rather awkward. The Java solutions to this have tended to be one of
- Define custom types for each intermediary stage—perhaps here we’d define a CustomerOrderGroup type.
- Chaining many operations together—adding more transformations onto the end of this chain
- Lose the type information
Now we don’t have to work around the problem, and can concisely represent our intermediary steps
var customerOrderGroups =
   from(customerList)
   .select(c -> tuple(
       c.companyName(),
       from(c.orders())
           .groupBy(o -> o.orderDate().year())
           .select(into((year, orders) -> tuple(
               year,
               from(orders)
                   .groupBy(o -> o.orderDate().month())
           )))
   ));
Impossible Types
The above example was impractical to represent due to being excessively long and obscure. Some types are just not possible to represent without type inference as they are anonymous.
The simplest example is an anonymous inner class
var person = new Object() {
   String name = "bob";
   int age = 5;
};

System.out.println(person.name + " aged " + person.age);
There’s no type that you could replace “var” with in this example that would enable this code to continue working.
Combining with the previous linq-style query example, this gives us the ability to have named tuple types, with meaningful property names.
var lengthOfNames  =
    from(customerList)
        .select(c -> new Object() {
            String companyName = c.companyName();
            int length = c.companyName().length();
        });

lengthOfNames.forEach(
    o -> System.out.println(o.companyName + " length " + o.length)
);
This also means it becomes more practical to create and use intersection types by mixing together interfaces and assigning to local variables
Here’s an example mixing together a Quacks and Waddles interface to create an anonymous Duck type.
public static void main(String... args) {
   var duck = (Quacks & Waddles) Mixin::create;
   duck.quack();
   duck.waddle();
}

interface Quacks extends Mixin {
   default void quack() {
       System.out.println("Quack");
   }
}

interface Waddles extends Mixin {
   default void waddle() {
       System.out.println("Waddle");
   }
}

interface Mixin {
   void __noop__();
   static void create() {}
}
This has more practical applications, such as adding behaviours onto existing types, ala extension methods
Encouraging Intermediary Variables
It’s now possible to declare variables with types that were erstwhile impractical or impossible to represent.
I hope that this leads to clearer code as it’s practical to add variables that explain the intermediate steps of transformations, as well as enabling previously impractical techniques such as the above.
A Russian translation of this post has been provided at Softdroid
The post Representing the Impractical and Impossible with JDK 10 “var” appeared first on Benji's Blog.

Connecting new screens

The new behavior is to now pop up a selection on-screen display (OSD) on the primary screen or laptop panel allowing the user to pick the new configuration and thereby make it clear what’s happening. When the same display hardware is plugged in again at a later point, this configuration is remembered and applied again (no OSD is shown in that case).
Another change-set which we’re about to merge is to pop up the same selection dialog when the user presses the display button which can be found on many laptops. This has been nagging me for quite a while since the display button switched screen configuration but provided very little in the way of visual feedback to the user what’s happening, so it wasn’t very user-friendly. This new feature will be part of Plasma 5.13 to be released in June 2018.
OSC interactive review
Requests are one of the staples for collaboration in the OBS. You can review via the webui or with OSC.
WebUI
Lets take the request listing for openSUSE:Factory. Your normal workflow will probably end up as
- middle mouse click on the little magnifying glass icon on the right.
- review the request in a new tab
- close the new tab
- go back step 1
My issues with the WebUI
- no advancing to the next request in my current list.
- I have to manually unfold/fold many diff chunks for a proper review.
- In the latest version of the WebUI: “We truncated the diff of some files because they were too big. If you want to see the full diff for every file, click here.” But even then I have to unfold every change myself again.
OSC - The normal way
- one terminal:
osc rq list -t submit -s new openSUSE:Factory - 2nd terminal:
osc rq show -d ID- the ID is taken from the first listing. - 2nd or in worst case 3rd terminal:
osc rq youraction ID - go back to step 2
My issues
- all manually copy pasting of IDs
OSC interactive mode
My config: