
LibreOffice GSoC user interface tasks
Working on a GSoC task has a real impact - for example the new LibreOffice 4.2 start center is the result of a GSoC task. Yes, the very face of new LibreOffice version is here thanks to Summer of Code.
I am going to mentor this year again, mostly user interface ideas. Let me summarize them here:
-
Improved Color Selection
Something that is really badly needed in LibreOffice. Selecting a color that is not pre-defined is a painful task for users - help us to finally improve the experience there! -
Further improvements in the Template manager
The Template manager is a result of an older GSoC task too. We would like to integrate it into the new Start center, to get a seamless experience for the user. -
Improve usability of Personas
This is a task to make the selecting the themes for your LibreOffice more pleasant, with better integration with Firefox Themes. -
Revamp the Gallery tool
This task will enable the user to browse online gallery of shapes, based on an older work that made this somehow possible.
If you want to apply for any of these, don't forget that we require you to solve a programming Easy Hack first; the more of them you do, the better chances you have that we will select you.
And if you have any questions, don't hesitate to ask :-)

About openQA and authentication
As you might have read in our previous post, our most important milestone in improving openQA is to make it possible to run the new version in public and accessible to everyone. To achieve this we need to add support for some form of authentication. This blog is about what we chose to support and why.
So what do we need?
openQA has several components that communicate with each other. The central point is the openQA server. It coordinates execution, stores the results and provides both the web interface for human beings and a REST-like API for the less-human beings. The REST API is needed for the so-called ‘workers’, which run the tests and send the results back to the server, but also for client command line utilities. Since this API can be used to schedule new tests, control job execution or upload results to the server, some kind of authentication is needed. We don’t want to write a whole article about REST authentication, but maybe some overview of the general problem could be useful to explain the chosen solution.
Authentication vs authorization
Let’s first clarify two related concepts: authentication vs authorization. Web authentication is easy when there is no API involved. You simply have a user and a password for accessing the service. You provide both to the server through your web browser so the server knows that you are the legitimate owner of the account, that’s all. That means a (hopefully different) combination of user and password for each service which is annoying and insecure. This is where openID comes into play. It allows any website to delegate authentication to a third party (an openID provider) so you can login in that website using your Google, Github or openSUSE account. In any case, it doesn’t matter if you are using a specific user, an openID user or another alternative system – authentication is always about proving to the server that you are the legitimate owner of the account so you can use it for whatever purpose in the website.
But, what about if you also provide a API meant to be consumed by applications instead of humans using a web browser? That’s where authorization comes into play. The owner of the account issues an authorization that can be used by an application to access a given subset of the information or the functionality. This authorization has nothing to do with the system used for real authentication. The application has no access to the user credentials (username or password) and is not impersonating the user in any way. It is just acting on his or her behalf for a limited subset of actions. The user can decide to revoke this authorization at any time (they usually simply expire in a certain period of time). Of course, a new problem arises: we need to verify that every request comes from a legitimately authorized entity.
Technologies we picked
We need a way to authenticate users, a way to authorize the client applications (like the workers) to act on their behalf and a way to check the validity of the authorizations. We could rely on the openSUSE login infrastructure (powered by Access Manager), but we want openQA to be usable and secure for everybody willing to install it. Without caring if he is inside or outside the openSUSE umbrella.
openID
There’s not much to say about user authentication; openID was the obvious choice. Open, highly standarized and supported and compatible with the openSUSE system and with some popular providers like Google or Github. And even more important, a great way to save ourself the work and the risk of managing user credentials.
authentication – harder
According to the level of popularity and standardization, the equivalent of openID for authorization would be oAuth, but a closer look into it revealed some drawbacks, complexity being the first. oAuth is also not free of controversy, resulting in three alternative specifications: 1.0, 1.0a and 2.0. Despite what the numbers suggest, different specifications are not just versions of the same thing, but different approaches to the problem that have their own supporters and detractors. Using oAuth would mean enabling the openQA server to be able to act as an oAuth provider and the different client applications to act as oAuth consumers. Aside from the complexity and various versions of the standard, one of the steps of the oAuth authorization flow (used for adding a new script or tool) is redirecting the user to the oAuth provider web page in order for him/her to explicitly authorize the application. Which means that a browser is needed, not nice at all when the consumer is a command line tool (usually executed remotely). We want to keep it simple and we don’t want to run a browser to configure the workers or any other client tool. Let’s look for less popular alternatives.
There are two sides to the authorization coin: identifying who is sending the request (and hence the privileges) and verifying that the request is legitimate and the server is not being cheated about that identity. The first part is usually achieved with an API key, a useful solution for open APIs in order to keep service volume under control, but not enough for a full authorization system. To achieve the second part, there is a strategy which is both easy to implement and safe enough for most cases: HMAC with a “shared secret”.
In short, every authorization includes two automatically generated hash keys, the already mentioned API key and an additional private one which is only known to the server and to the application using that authorization. In each request, several headers are added: at least one with the timestamp of the request, another with the API key and a third one which is the result of applying an encryption algorithm (such as SHA-1) to the request itself (including the timestamp and the parameters) using the private hash as salt. In the server, queries with old timestamps are discarded. For fresh requests, the API key header is used to determine the associated private key and the same encryption algorithm is applied to the query, checking the result against the corresponding header to verify both the integrity of the request and the legitimacy of the sender.
We decided to go for this as it is both simple and secure enough for our use case. Of course, the private key still needs to be stored both server and client side, but it’s not the users’ password. It’s just a random shared secret with no relation to the real user credentials or identity. It also can be revoked at any point and can only be used for actions like upload a test result or cancel a job. Secure enough for a system like openQA, with no personal information stored and no critical functionality exposed.
Conclusion
So, we’ve implemented openID and are working on a lightweight HMAC based authorization system. Next week we’ll update you on the other things we are working on, including our staging projects progress!
Goodbye EC2 Tools Long Live AWS Tools
For quite some time we had a package named ec2-api-tools in the Cloud:EC2 project and I suspect many that work with EC2 had found the package and were using the ec2-* commands to manage stuff in EC2. Along with the ec2-api-tools Amazon maintained a separate ec2-* tool set for various services. Keeping up with the armada of Amazon developers is not easy and thus the other ec2-* tool sets never got packaged.
Now a new integrated set of tools is available called with the “aws” command and provided by the aws-cli package. The package is available from the Cloud:Tools project and a submit request to Factory is pending. The new package does not obsolete the ec2-api-tools package as there is no issue with having both packages installed. However, I did take the liberty to remove the ec2-api-tool package from the Cloud:EC2 project as it would no longer receive updates considering that we have a nice new tool that unifies all Amazon services. The documentation for the new command can be found .
The aws code is hosted on github and thus contribution of fixes is easy and that is another big plus over the ec2-* tool sets.
Yes, and of course we need to get openSUSE 13.1 into EC2, and I am working on that, stay tuned….

 Member
 FunkyPenguin
Working with openSUSE's Kernel Source

GNOME.Asia summit 2014 is call for paper

PRESENTING AT THE GNOME.ASIA SUMMIT
- GNOME Marketing
- Promotion of Free / Open Source Software
- How to run a Local GNOME Users Group
- Asia success stories / Local GNOME Projects
- GNOME and Educations
- GNOME Outreach Program for Women
- Google Summer of Code
- Latest developments in GNOME
- GNOME 3 & GNOME 3 Usability
- GNOME Human Interface Engineering (Icons and Graphic Design)
- QA and testing in GNOME
- GNOME Accessibility
- GNOME Coding How-to
- Writing applications for GNOME 3
- Integration of web life into the desktop
- Developing GNOME on mobile devices (smart phones, tablets)
- Developing GNOME on embedded systems or open source hardware
- On-going projects and success stories
- Finding Free and Open Source friendly hardware manufacturers
- Translations
- Input methods
- Fonts
CVE-2104-0081 timeline
12.Feb.2014 - 02:36 CET - Rafael Modença França commits the fix (private)[1]
14.Feb.2014 - 21:41 CET - RedHat create bugzilla entry (private)[2]
18.Feb.2014 - 17:06 CET - SUSE creates bugzilla entry (private)[3]
18.Feb.2014 - 20:00 CET - Rafael Modença França merges the fix to master[4]
- version 4.1.0.beta2 is released [5]
- version 4.0.3 is released [5]
- version3.2.17 is released [5]
18.Feb.2014 - 20:03 CET - aaron patterson sends email to rubyonrails-security@googlegroups.com, oss-security@lists.openwall.com, secalert@redhat.com[6][7]
18.Feb.2014 - 20:10 CET - redruby.io service sends me an email[8]
18.Feb.2014 - 20:12 CET - aaron patterson sends email to ruby-security-ann@googlegroups.com[9]
18.Feb.2014 - 20:17 CET - Rafael França publishes on weblog.rubyonrails.org [10]
18.Feb.2014 - 20:33 CET - hakiri.io service sends me an email[11]
18.Feb.2014 - 20:36 CET - holepicker adds the security alerts in its database[12]
18.Feb.2014 - 21:06 CET - hacker news publishes in its blog[13]
18.Feb.2014 - 21:38 CET - RedHat removes embargoed[2]
19.Feb.2014 - 03:30 CET - Added to osvdb[14]
19.Feb.2014 - 09:03 CET - SUSE removes embargoed[3]
19.Feb.2014 - 11:49 CET - gemnasium.com sends me an email [15]
20.Feb.2014 - 15:24 CET - ruby weekly publishes the new (ruby weekly is released every Thursday)[16]
[1] https://github.com/rails/rails/commit/08d0a11a3f62718d601d39e617c834759cf59bbb
[2] https://bugzilla.redhat.com/show_bug.cgi?id=1065520
[3] https://bugzilla.novell.com/show_bug.cgi?id=864433
[4] https://github.com/rails/rails/commit/1879c259b870938c42d5d52f63123bfa0b8c81c8
[5] http://rubygems.org/gems/rails/versions
[6] https://groups.google.com/forum/#!topic/rubyonrails-security/tfp6gZCtzr4
[7] http://www.openwall.com/lists/oss-security/2014/02/18/8
[8] https://www.redruby.io
[9] https://groups.google.com/forum/#!topic/ruby-security-ann/1PWnwW4jRkY
[10] http://weblog.rubyonrails.org/2014/2/18/Rails_3_2_17_4_0_3_and_4_1_0_beta2_have_been_released/
[11] https://haikiri.io
[12] https://github.com/jsuder/holepicker/commits/master/lib/holepicker/data/data.json
[13] https://www.facebook.com/hnbot
[14] http://osvdb.org/103439
[15] https://gemnasium.com
[16] http://rubyweekly.com
El model de negoci del software lliure a Berga el 27 de Març

El 27 de Març a les 18:00 de la tarda faré una presentació al coworking loficina (loficina.cat) sobre com fer negoci amb software lliure. Animeu-vos a venir :) !
How can one catch OS X sandbox violations in a debugger?
Do you know of any way to catch OS X sandbox violations as they happen (in a huge program like LibreOffice where you don't have a clue what is going on in all places in the codebase) in a debugger (either gdb on the command line, or lldb under Xcode)? The trick using Dtrace in https://devforums.apple.com/message/874181#874181 does not seem to work in 10.9.1 at least.
FOSDEM14 lima driver talk.
Luckily, some people from the sunxi community took the livestream of sunxi related talks, and produced some quick dumps of it. I have now copied the Mali driver talk over to my fd.o account so that the sunxi server doesn't become too overloaded. Slides are also available.
This talk mentions where i am at with my mesa driver, why i am taking the route i am taking, the importance of SoC communities, and how the lack thereof hampers driver development, and also talks about the company ARM and their stance towards the open driver.
Enjoy!
First fruits – update on openQA and Staging work
In our previous summary, we talked about some basic research and some ground work to build on. This time we have some first exciting results!
openQA
Last week we rearranged the repository a little bit, creating a new branch called "devel" where all the exciting (and not so exciting) changes are taking place. Our little Factory 
The main difference between this branch as master is that, as you could read in the previous blog, the devel branch is openQA build on Mojolicious, a nice web development framework. And having a proper web framework is starting to show its benefits: we have openID login available! Unfortunately the current openSUSE openID provider is a little bit weird, so it doesn’t play well with our tool yet, but some others are working and openSUSE accounts will be the next step. Having working user accounts is necessary to be able to start defining permissions and to make openQA truly multiuser. And to be able to deploy the new version on a public server!
The other main focus of this week has been internal polishing. We have revamped the database layout and changed the way in which the different openQA components communicate with each other. The openQA functionality is spread out over several parts: the workers are responsible of actually executing the tests in virtual machines reporting the result after every execution; some client utilities are used to load new ISO images and similar tasks and, finally, we have the one openQA Server to rule them all. Until now, the communication between the server and the other components was done using JSON-RPC (a lightweight alternative to XML-RPC). We have dropped JSON-RPC in favor of a REST-like API with just JSON over plain HTTP. This change allowed us to implement exactly the same functionality in a way that is simpler, perfectly supported by any web framework, natively spoken by browsers and easier to authenticate (using, for example, plain HTTP authentication or openID). This is also the first step to future integration with other services (think OBS, as the ultimate goal is to use openQA to test staging projects).
But, who tests the tester? openQA is growing and changing quite fast so we have continued with the task of creating a good testing infrastructure to tests openQA itself to make sure that all our changes do not result in breakage. We only have a few tests right now, but we now have a solid foundation to write more and more tests.
Staging and package manipulation
In the last blog post we told you we were investigating a code test suite to test the abilities of a osc plugin we are writing. osc is the commandline tool for handling the Open Build Service, and this plugin is meant to help with the administration of staging projects. We’ve been thinking about how to move forward with the testing part as we want to make sure the functionality works as advertised. More important, we write tests to make sure that our additions and changes do not break existing functionality. We have started merging functionality from various scripts handling staging thingies and rings we had into this plugin. This is partially done so we can do basic staging project tasks! We can take a request (be it submit or delete) and put it to test in a staging project. We can also move packages between staging projects and we have a simple YAML in project descriptions to indicate what packages and what requests are there.
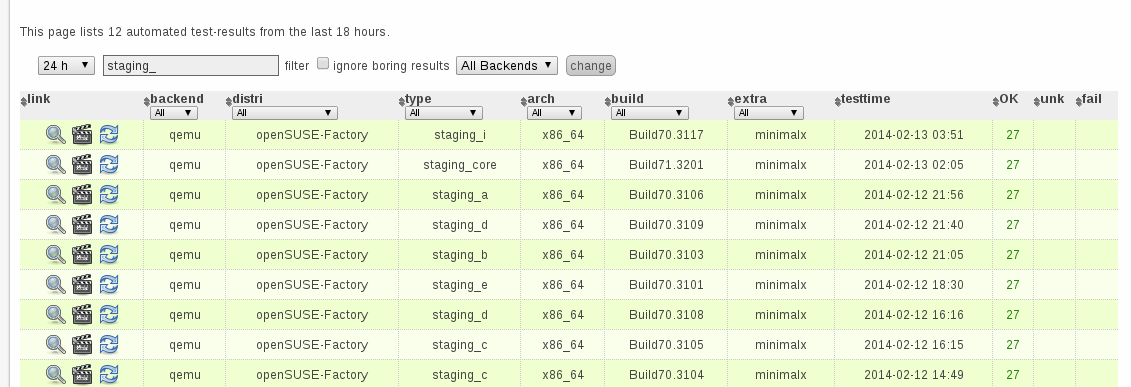
Coolo already started using the plugin for some tasks, so you can see pretty titles and metadata in staging projects descriptions. Not impressive enough? Let me provide you a good headline:
Thanks to staging projects, no single regression have been introduced this year in the core of Factory
You can enjoy a more detailed description in this announcement written by coolo to the Factory mailing list and have some visual joy in the included screenshot (genuine pr0n for QA engineers).
Last but not least, we also did some cleanup of the sources in the repo and of course we added more tests (as functionality grows). And there has been work on other parts of the plugin, like taking rings into account.
Result
We already have some useful functionality which we are going to expand and build on. Not that much to show yet, but we are progressing towards our goal. You can follow our progress either in the way of tasks (openQA and staging projects) or just follow our commit history on github (again for both openQA and staging plugin).
We are very much looking forward to feedback and thoughts – these changes aim to make Factory development easier and thus we need to hear from all you!