
 Member
 baltolkien
Escape to Freedom, vídeo de la Free Software Foundation
Me complace presentar» Escape to Freedom», un vídeo de la Free Software Foundation que publicó en el 2022 y que intenta hacernos reflexionar sobre la necesidad de tener un control sobre nuestra vida digital para tener nuestros derechos fundamentales protegidos.
Escape to Freedom, vídeo de la Free Software Foundation
El mundo del Software Libre es mucho más grande de lo que pensamos, y es que para los humanos el número de humanos que hay en el mundo es un concepto que no podemos procesar bien. Solo tenéis que ir un día a una estación de tren o a un aeropuerto para comprobar la cantidad de trenes/aviones que circulan, pensar que la mayoría van llenos y después reflexionar que cada una de las personas que veis tiene una vida similar a la vuestra, con sus familiares, amigos y conocidos para poder vislumbrar cuánta gente somos.
Esta reflexión da pie a entender que en esto del Software Libre, a pesar de que cuando se hace algún evento parece que somos cuatro gatos, en realidad detrás hay centenares de personas que sí están interesadas y que participan activamente en su desarrollo.
Esto explica cosas como la gran cantidad de proyectos de Software Libre que hay en el mundo, un número creciente a pesar de las dificultades tecnológicas y, por qué no decirlo, políticas que en vez de remar a favor de la protección de los derechos de los individuos buscan como sacar provecho económico de cualquier circunstancia.
Todo lo anterior era un poco para justificarme por no presentar este vídeo antes ya que cualquier cosa que sea por promocionar el Software Libre a niveles bajos es fundamental si alguna vez queremos que nuestra sociedad se vuelva mucho más seria y responsable.
Pero bueno, me voy del tema. Hoy quería compartir con vosotros un vídeo que ya tiene dos años y que lleva por título «Escape To Freedom». Una creación de la Free Software Foundation (FSF) y que pretende ser una introducción a los conceptos que subyacen a la libertad del software: qué ganamos con ella y qué derechos están en juego.
En palabras de la FSF:
Este vídeo es la última incorporación a la serie de vídeos animados creados por la FSF sobre el tema del software libre. Pensamos en Escape to Freedom como una fábula que demuestra las consecuencias demasiado reales de no tener control sobre tu propia informática, y lo importante que es nuestra lucha colectiva por la liberación digital.
Al trabajar esta vez con un estilo de animación surrealista, esperamos haber ilustrado de forma evocadora algunos de los efectos emocionales que el software no libre y la falta de control sobre la propia autonomía digital pueden tener en la vida cotidiana.
Escape to Freedom muestra a los enemigos monopolistas del movimiento con una lente inquietante, pero esperamos que esta distorsión de la realidad ayude a mostrarlos tal y como son en realidad. Escape to Freedom presenta el movimiento siguiendo la tradición de la alegoría, y describe la necesidad de la libertad del software de forma que capte la atención de los usuarios de ordenadores sin conocimientos técnicos.
Help others find free software: Watch and share Escape to Freedom by Greg Farough
Bien, no os mareo más y os dejo el vídeo, el cual creo que es un buen material para poder concienciar a aquellas personas que todavía no son conscientes de la importancia del Software Libre en sus vidas.
¿Que es la FSF?
Por no hacer más larga la entrada, la La Free Software Foundation (FSF) es una entidad sin ánimo de lucro con la misión de promover mundialmente la libertad de los usuarios de computadores y defender los derechos de todos los usuarios de software libre.
Tiene una intensa actividad y os aconsejo visitar su página web para poder sacar provecho de todo lo que ofrece: información, materiales, contactos, etc.
Más información: FSF
La entrada Escape to Freedom, vídeo de la Free Software Foundation se publicó primero en KDE Blog.
Build Results Summary Chart Links to Build Results Overview
Vuelve el evento24H24L edición 2024
Todo cambia, y esa es la constantedel evento 24H24L, que ha pasado de ser un evento intensivo a una serie de charlas puntuales publicadas en un solo día a los mismo pero que no espera y que se van publicando a medida que se graban. En otras palabras, vuelve el evento 24H2L edición 2024 donde destacados (o no tnato porque participo yo) miembros de la Comunidad hablan de forma distendida sobre diversos aspectos del mundo del Software Libre. Estos audios tienen la intención de ser una puerta de entrada para todo el mundo, así que son 10%% recomendable a los nuevos o potenciales usuarios.
Vuelve el evento24H24L edición 2024

Este año José Jiménez, promotor de esta iniciativa, vuelve a dar otra vuelta y se está dedicando a realizar charlas puntuales y las va publicando poco a poco. De hecho, os comporto el rss para que las vayáis escuchando a medida que se van publicando a que después se acumulan y colapsan de GNU/Linux nuestros podcaster.
Debo reconocer que tengo pendiente de escuchar todavía muchas de ellas, incluso de la edición del 2021, pero que todos los que escucho me parecen de los más interesantes por la variedad de temas y la calidad de los contertulios.
Además, este año, debido a que algunos se han grabado en febrero los participantes han destacado algún proyecto de Software Libre al que darle las gracias, lo cual hace que no solo se hable de los temas especializados de los colaboradores sino que se multilpique por dos o tres las iniciativas presentadas, aunque sea solo dando una pincelada.
En palabras de su promotor:
El evento 24H24L consiste en la grabación de 24 audios de 1 hora sobre una temática especifica, en esta tercera edición se centrará en GNU/Linux. El propósito es cualquier usuario independientemente de su nivel descubra que le puede aportar este sistema operativo y le facilite el camino para empezar a utilizar este sistema.
Y, como es habitual en este tipo de entradas, os pongo aquí mismo la charla extraída del canal de PeerTube de 24H24L que tiene en FediverseTV, al cual os pido encarecidamente que le deis un vistazo.
Aprovecho para poner algunos enlaces de interés para poder disfrutar de esta iniciativa que ya lleva mucho tiempo promocionando el Software Libre y en la que espero poder partcipar pronto.
Más información: 24H24L
La entrada Vuelve el evento24H24L edición 2024 se publicó primero en KDE Blog.

Rustifying libipuz: character sets
It has been, what, like four years since librsvg got fully rustified, and now it is time to move another piece of critical infrastructure to a memory-safe language.
I'm talking about libipuz, the GObject-based C library that GNOME Crosswords uses underneath. This is a library that parses the ipuz file format and is able to represent various kinds of puzzles.
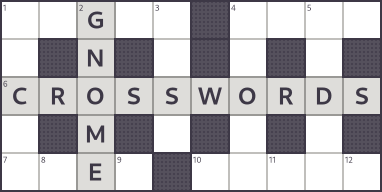
Libipuz is an interesting beast. The ipuz format is JSON with a lot of hair: it needs to represent the actual grid of characters and their solutions, the grid's cells' numbers, the puzzle's clues, and all the styling information that crossword puzzles can have (it's more than you think!).
{
    "version": "http://ipuz.org/v2",
    "kind": [ "http://ipuz.org/crossword#1", "https://libipuz.org/barred#1" ],
    "title": "Mephisto No 3228",
    "styles": {
        "L": {"barred": "L" },
        "T": {"barred": "T" },
        "TL": {"barred": "TL" }
    },
    "puzzle":   [ [  1,  2,  0,  3,  4,  {"cell": 5, "style": "L"},  6,  0,  7,  8,  0,  9 ],
                  [  0,  {"cell": 0, "style": "L"}, {"cell": 10, "style": "TL"},  0,  0,  0,  0,  {"cell": 0, "style": "T"},  0,  0,  {"cell": 0, "style": "T"},  0 ]
                # the rest is omitted
    ],
    "clues": {
        "Across": [ {"number":1, "clue":"Having kittens means losing heart for home day", "enumeration":"5", "cells":[[0,0],[1,0],[2,0],[3,0],[4,0]] },
                    {"number":5, "clue":"Mostly allegorical poet on writing companion poem, say", "enumeration":"7", "cells":[[5,0],[6,0],[7,0],[8,0],[9,0],[10,0],[11,0]] },
                ]
        # the rest is omitted
    }
}
Libipuz uses json-glib, which works fine to ingest the JSON into memory, but then it is a complete slog to distill the JSON nodes into C data structures. You need iterate through each node in the JSON tree and try to fit its data into yours.
Get me the next node. Is the node an array? Yes? How many elements? Allocate my own array. Iterate the node's array. What's in this element? Is it a number? Copy the number to my array. Or is it a string? Do I support that, or do I throw an error? Oh, don't forget the code to meticulously free the partially-constructed thing I was building.
This is not pleasant code to write and test.
Ipuz also has a few mini-languages within the format, which live inside string properties. Parsing these in C unpleasant at best.
Differences from librsvg
While librsvg has a very small GObject-based API, and a medium-sized library underneath, libipuz has a large API composed of GObjects, boxed types, and opaque and public structures. Using libipuz involves doing a lot of calls to its functions, from loading a crossword to accessing each of its properties via different functions.
I want to use this rustification as an exercise in porting a moderately large C API to Rust. Fortunately, libipuz does have a good test suite that is useful from the beginning of the port.
Also, I want to see what sorts of idioms appear when exposing things
from Rust that are not GObjects. Mutable, opaque structs can just
be passed as a pointer to a heap allocation, i.e. a Box<T>. I want
to take the opportunity to make more things in libipuz immutable;
currently it has a bunch of reference-counted, mutable objects, which
are fine in single-threaded C, but decidedly not what Rust would
prefer. For librsvg it was very beneficial to be able to notice parts
of objects that remain immutable after construction, and to
distinguish those parts from the mutable ones that change when the
object goes through its lifetime.
Let's begin!
In the ipuz format, crosswords have a character set or charset: it is the set of letters that appear in the puzzle's solution. Internally, GNOME Crosswords uses the charset as a histogram of letter counts for a particular puzzle. This is useful information for crossword authors.
Crosswords uses the histogram of letter counts in various important
algorithms, for example, the one that builds a database of words
usable in the crosswords editor. That database has a clever
format which allows answering questions like the following
quickly: What words in the database match ?OR?? — WORDS and
CORES will match.
IPuzCharset is one of the first pieces of code I worked on in
Crosswords, and it later got moved to libipuz. Originally it didn't
even keep a histogram of character counts; it was just an ordered set
of characters that could answer the question, "what is the index of
the character ch within the ordered set?".
I implemented that ordered set with a GTree, a balanced
binary tree. The keys in the key/value tree were the characters, and
the values were just unused.
Later, the ordered set was turned into an actual histogram with character counts: keys are still characters, but each value is now a count of the coresponding character.
Over time, Crosswords started using IPuzCharset for different
purposes. It is still used while building and accessing the database
of words; but now it is also used to present statistics in the
crosswords editor, and as part of the engine in an acrostics
generator.
In particular, the acrostics generator has been running into some
performance problems with IPuzCharset. I wanted to take the port to
Rust as an opportunity to change the algorithm and make it faster.
Refactoring into mutable/immutable stages
IPuzCharset started out with these basic operations:
/* Construction; memory management */
IPuzCharset          *ipuz_charset_new              (void);
IPuzCharset          *ipuz_charset_ref              (IPuzCharset       *charet);
void                  ipuz_charset_unref            (IPuzCharset       *charset);

/* Mutation */
void                  ipuz_charset_add_text         (IPuzCharset       *charset,
                                                     const char        *text);
gboolean              ipuz_charset_remove_text      (IPuzCharset       *charset,
                                                     const char        *text);

/* Querying */
gint                  ipuz_charset_get_char_index   (const IPuzCharset *charset,
                                                     gunichar           c);
guint                 ipuz_charset_get_char_count   (const IPuzCharset *charset,
                                                     gunichar           c);
gsize                 ipuz_charset_get_n_chars      (const IPuzCharset *charset);
gsize                 ipuz_charset_get_size         (const IPuzCharset *charset);
All of those are implemented in terms of the key/value binary tree that stores a character in each node's key, and a count in the node's value.
I read the code in Crosswords that uses the ipuz_charset_*()
functions and noticed that in every case, the code first constructs
and populates the charset using ipuz_charset_add_text(), and then
doesn't modify it anymore — it only does queries afterwards. The only
place that uses ipuz_charset_remove_text() is the acrostics
generator, but that one doesn't do any queries later: it uses the
remove_text() operation as part of another algorithm, but only that.
So, I thought of doing this:
-
Split things into a mutable
IPuzCharsetBuilderthat has theadd_text/remove_textoperations, and also has abuild()operation that consumes the builder and produces an immutableIPuzCharset. -
IPuzCharsetis immutable; it can only be queried. -
IPuzCharsetBuildercan work with a hash table, which turns the "add a character" operation from O(log n) to O(1) amortized. -
build()is O(n) on the number of unique characters and is only done once per charset. -
Make
IPuzCharsetwork with a different hash table that also allows for O(1) operations.
Basics of IPuzCharsetBuilder
IPuzCharsetBuilder is mutable, and it can live on the Rust side as a
Box<T> so it can present an opaque pointer to C.
#[derive(Default)]
pub struct CharsetBuilder {
    histogram: HashMap<char, u32>,
}

// IPuzCharsetBuilder *ipuz_charset_builder_new (void); */
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_builder_new() -> Box<CharsetBuilder> {
    Box::new(CharsetBuilder::default())
}
For extern "C", Box<T> marshals as a pointer. It's nominally what
one would get from malloc().
Then, simple functions to create the character counts:
impl CharsetBuilder {
    /// Adds `text`'s character counts to the histogram.
    fn add_text(&mut self, text: &str) {
        for ch in text.chars() {
            self.add_character(ch);
        }
    }

    /// Adds a single character to the histogram.
    fn add_character(&mut self, ch: char) {
        self.histogram
            .entry(ch)
            .and_modify(|e| *e += 1)
            .or_insert(1);
    }
}
The C API wrappers:
use std::ffi::CStr;

// void ipuz_charset_builder_add_text (IPuzCharsetBuilder *builder, const char *text);
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_builder_add_text(
    builder: &mut CharsetBuilder,
    text: *const c_char,
) {
    let text = CStr::from_ptr(text).to_str().unwrap();
    builder.add_text(text);
}
CStr is our old friend that takes a char * and can wrap it as a
Rust &str after validating it for UTF-8 and finding its length.
Here, the unwrap() will panic if the passed string is not UTF-8, but
that's what we want; it's the equivalent of an assertion that what was
passed in is indeed UTF-8.
// void ipuz_charset_builder_add_character (IPuzCharsetBuilder *builder, gunichar ch);
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_builder_add_character(builder: &mut CharsetBuilder, ch: u32) {
    let ch = char::from_u32(ch).unwrap();
    builder.add_character(ch);
}
Somehow, the glib-sys crate doesn't have gunichar, which is just a
guint32 for a Unicode code point. So, we take in a u32, and check
that it is in the appropriate range for Unicode code points with
char::from_u32(). Again, a panic in the unwrap() means that the
passed number is out of range; equivalent to an assertion.
Converting to an immutable IPuzCharset
pub struct Charset {
    /// Histogram of characters and their counts plus derived values.
    histogram: HashMap<char, CharsetEntry>,

    /// All the characters in the histogram, but in order.
    ordered: String,

    /// Sum of all the counts of all the characters.
    sum_of_counts: usize,
}

/// Data about a character in a `Charset`.  The "value" in a key/value pair where the "key" is a character.
#[derive(PartialEq)]
struct CharsetEntry {
    /// Index of the character within the `Charset`'s ordered version.
    index: u32,

    /// How many of this character in the histogram.
    count: u32,
}

impl CharsetBuilder {
    fn build(self) -> Charset {
        // omitted for brevity; consumes `self` and produces a `Charset` by adding
        // the counts for the `sum_of_counts` field, and figuring out the sort
        // order into the `ordered` field.
    }
}
Now, on the C side, IPuzCharset is meant to also be immutable and
reference-counted. We'll use Arc<T> for such structures. One
cannot return an Arc<T> to C code; it must first be converted to a
pointer with Arc::into_raw():
// IPuzCharset *ipuz_charset_builder_build (IPuzCharsetBuilder *builder);
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_builder_build(
    builder: *mut CharsetBuilder,
) -> *const Charset {
    let builder = Box::from_raw(builder); // get back the Box from a pointer
    let charset = builder.build();        // consume the builder and free it
    Arc::into_raw(Arc::new(charset))      // Wrap the charset in Arc and get a pointer
}
Then, implement ref() and unref():
// IPuzCharset *ipuz_charset_ref (IPuzCharset *charet);
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_ref(charset: *const Charset) -> *const Charset {
    Arc::increment_strong_count(charset);
    charset
}

// void ipuz_charset_unref (IPuzCharset *charset);
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_unref(charset: *const Charset) {
    Arc::decrement_strong_count(charset);
}
The query functions need to take a pointer to what really is the
Arc<Charset> on the Rust side. They reconstruct the Arc with
Arc::from_raw() and wrap it in ManuallyDrop so that the Arc
doesn't lose a reference count when the function exits:
// gsize ipuz_charset_get_n_chars (const IPuzCharset *charset);
#[no_mangle]
pub unsafe extern "C" fn ipuz_charset_get_n_chars(charset: *const Charset) -> usize {
    let charset = ManuallyDrop::new(Arc::from_raw(charset));
    charset.get_n_chars()
}
Tests
The C tests remain intact; these let us test all the #[no_mangle] wrappers.
The Rust tests can just be for the internals, simliar to this:
    #[test]
    fn supports_histogram() {
        let mut builder = CharsetBuilder::default();

        let the_string = "ABBCCCDDDDEEEEEFFFFFFGGGGGGG";
        builder.add_text(the_string);
        let charset = builder.build();

        assert_eq!(charset.get_size(), the_string.len());

        assert_eq!(charset.get_char_count('A').unwrap(), 1);
        assert_eq!(charset.get_char_count('B').unwrap(), 2);
        assert_eq!(charset.get_char_count('C').unwrap(), 3);
        assert_eq!(charset.get_char_count('D').unwrap(), 4);
        assert_eq!(charset.get_char_count('E').unwrap(), 5);
        assert_eq!(charset.get_char_count('F').unwrap(), 6);
        assert_eq!(charset.get_char_count('G').unwrap(), 7);

        assert!(charset.get_char_count('H').is_none());
    }
Integration with the build system
Libipuz uses meson, which is not particularly fond of
cargo. Still, cargo can be used from meson with a wrapper script
and a bit of easy hacks. See the merge request for details.
Further work
I've left the original C header file ipuz-charset.h intact, but
ideally I'd like to automatically generate the headers from Rust with
cbindgen. Doing it that way lets me check that my
assumptions of the extern "C" ABI are correct ("does foo: &mut Foo
appear as Foo *foo on the C side?"), and it's one fewer C-ism to
write by hand. I need to see what to do about inline documentation;
gi-docgen can consume C header files just fine, but I'm
not yet sure about how to make it work with generated headers from
cbindgen.
I still need to modify the CI's code coverage scripts to work with the mixed C/Rust codebase. Fortunately I can copy those incantations from librsvg.
Is it faster?
Maybe! I haven't benchmarked the acrostics generator yet. Stay tuned!

My Igalia Coding Experience 2023 I & II at Wolvic
Wolvic is a fast and secure browser for standalone virtual-reality and augmented-reality headsets. ex. Mozilla Firefox Reality.
Project summaries
- Develop VR Browser, refactor Android deprecated methods
- Address user issues. Implement UI, graphics, browser, and openXR related features
- Contribute to the majority of the features available from v1.4.2 – 1.6:
List of things I have done
PRs opened/handled
- (merged) #773 Fix build with JDK 17
- (closed) #787 Fix and Check warnings / deprecation notes in the current build
- (closed) #796 Fix deprecated android.inputmethodservice.Keyboard and keyboardView
- (merged) #811 Fix and Check warnings / deprecation notes in the current build
- (merged) #812 Fix deprecated android.inputmethodservice.Keyboard and keyboardView
- (merged) #814 Fix dependabot.yml syntax
- (merged) #820 Upgrade Android dependencies
- (reviewed) #829 Initial flow for mainland China
- (reviewed) #831 Use androidx’s PreferenceManager
- (reviewed) #621 Add some dependency conflict resoluton strategies
- (merged) #838 Fix keyboard icon displaying
- (reviewed) #824 [l10n] Update translations to Chinese (Simplified)
- (merged) #843 Support per-architecture dependency substitutions for Gecko
- (merged) #844 Implement POST resubmission confirmation
- (closed) #848 Homepage bypass cache so that it can work corectly after a language change
- (reviewed) #816 Bump com.android.tools.build:gradle from 4.2.2 to 8.0.2
- (reviewed) #781 Remove WaveVR build dependency
- (merged) #852 Fix several issues related to Download List
- (merged) #853 Use left alignment for the download Confirmation Dialog
- (merged) #854 Modernize deprecated setSystemUiVisibility(int) and related flags
- (merged) #855 Make keyboard follow the system locale if never manual select
- (reviewed) #856 [HVR] Make PlatformActivity inherit form Activity again
- (reviewed) #819 Bump net.lingala.zip4j:zip4j from 1.3.2 to 2.11.5
- (closed) #859 Ask OpenXR runtime for available GL formats options
- (closed) #860 Replace kAverageHeight with XR_REFERENCE_SPACE_TYPE_STAGE
- (merged) #862 Fix Android tests
- (reviewed) #866 Remove overlay extension support for Pico
- (reviewed) #640 Ana2k/date time picker
- (merged) #877 Implement DateTime picker Dialog
- (merged) #878 Fix to keep the selected options for <select>
- (reviewed) #876 Meta store fixes
- (merged) #879 File:// uri navigation support
- (merged) #880 Use getNonAutocompleteText to fix awesomebar
- (opened) #881 Reorganize Libraries and add search UI in panels
- (reviewed) #882 Support using maven GV from the release channel
- (merged) #883 Continue upgrading some deprecated methods
- (merged) #885 Fix Language change issues when change language in Wolvic
- (reviewed) #892 Use geckoview-nightly by default
- (merged) #893 Migrate from org.mozilla.components:browser-search to feature-search
- (reviewed) #895 Only pass valid URIs to loadUri
- (reviewed) #903 Remove duplicated code from HandMeshRendererSkinned class
- (merged) #906 Modernize deprecated CONNECTIVITY_ACTION in ConnectivityManager
- (reviewed) #908 Fix a crash when retrieving WifiInfo
- (merged) #910 Add a null check to getSignalStrength()
- (reviewed) #912 Create FUNDING.yml
- (merged) #913 Fix opencollective funding link
- (reviewed) #914 Fix white flashes in several (heavy) WebXR experiences while in immersive mode
- (merged) #917 Upgrade Android Components to 116
- (reviewed) #918 [Chromium] Pass the correct URL to onPageStart
- (closed) #930 Copy search engine list from upstream and add yandex when Russian
- (reviewed) #935 Fix a crash when drawing hands before updating mesh in HandMeshRenderSkinned
- (reviewed) #936 Revert “Modernize deprecated CONNECTIVITY_ACTION in ConnectivityManager”
- (merged) #946 Fix disabling address bar auto-complete feature in settings
- (merged) #947 Implement Find in Page
- (merged) #950 Fix restarting Wolvic
- (merged) #952 Use red color when no search result for find in page
- (reviewed) #953 [Chromium] SessionFinder: fix a startup crash
- (reviewed) #954 New approach to handle remote environments
- (merged) #958 Open the feedback form in a new window
- (merged) #959 Some minor improvements for Find in page
- (merged) #960 Allow open new page without interrupting video playing
- (reviewed) #643 Workaround for YouTube videos
- (merged) #961 Fix Youtube captions
- (merged) #966 Fix WiFi Icon when starting Wolvic with no WiFi
- (closed) #968 Bypass download uri cache when user tries to download again
- (merged) #969 Fix 3D Side-By-Side video playing in curved mode
- (reviewed) #971 [NoAPI] Enable on screen rendering
- (merged) #972 Refactor CI
- (merged) #973 [NoAPI] Fix control panels
- (merged) #974 Remove Find In Page Item when in kiosk mode
- (reviewed) #978 Upgrade R8 to version 8.2
- (reviewed) #979 [NoAPI] Enable WebXR and other fixes to the native lib
- (merged) #980 Add back Find In Page when in kiosk mode
- (merged) #982 Select tab when opening URL foreground by intent
- (opened) #983 Use versionCodeToDate again in Settings dialog
- (opened) #984 [OpenXR] OpenXRLayer move Destroy() to destructors
- (reviewed) #997 Cancel find in page on navigation
- (reviewed) #996 Improve detection of URLs with long gTLDs
- (reviewed) #999 [OpenXR] Use XR_FB_hand_tracking_aim to get trigger pinch status and factor on Quest
- (merged) #1000 Enable starting with passthrough mode
- (merged) #1004 Enable to use system trusted root certificates
- (reviewed) #1006 Replace Manifest’s attributes instead of the whole node
- (merged) #1007 Enable voice input from keyboard
- (merged) #1008 Add 3D top bottom format support to VR video playing
- (merged) #1009 Add 2D option to projection menu to allow exit to full screen
- (merged) #1010 Move page loading progress bar around the refresh button
- (opened) #1012 Enable desktop mode as the User-Agent
- (merged) #1014 Make voice input content scrollable and stick to the latest
- (reviewed) #1015 [HVR] Do not request the WiFi SSID for mainland China packages
- (merged) #1017 Improve some UI user experience
- (merged) #1018 Use horizontal layout for DateTime picker prompt
- (merged) #1021 Fix several issues related to seek bar for VR video playing
- (reviewed) #1020 Move homepage URL to a resValue in build config
- (reviewed) #1022 [HVR] Fix flavor detection when deciding about requesting SSID
- (merged) #1025 Add option to clear all user data
- (merged) #1026 Add back the mute/unmute control in VR video control
- (merged) #1027 Fix Youtube video pause when entering immersive mode
- (merged) #1028 Allow exit find in page mode when we press the back button
- (merged) #1030 Fix Chinese/Japanese keyboard typing
- (merged) #1031 Use context.getCacheDir() to store unzipped environment files
- (merged) #1032 Allow YouTube playing different projection types of VR videos continuously
- (merged) #1033 Fix voice search default language selection
- (merged) #1034 Upgrade Android Component to 121.1.0 & AGP to 8.2.1
- (reviewed) #259 Do not instantiate the Runtime in crash reporter service
- (reviewed) #1 Added INTERNET permissions to the manifest
- (reviewed) #734 Change the window distance
- (merged) #1036 Set tray date displaying format without hardcoding
- (merged) #1046 Implement audio engine using Android Media Player
- (merged) #1047 Allow jumping to the video start/end by clicking on time labels
- (reviewed) #1049 Updated App Lab warning message
- (merged) #1050 Enable drag and move windows at X & Y direction
- (merged) #1057 Fix several issues related to VR videos playing
- (merged) #1063 Enable seeking VR video through controller D-pad
- (merged) #1064 Remove duplicated suggestions in awesome bar
- (merged) #1068 Enable haptic feedback for controllers
- (merged) #1071 Improve Device Name in Firefox/Mozilla Sync
- (merged) #1072 Rename Firefox account into Mozilla accounts in translations
- (merged) #1073 [NoAPI] Reorganize the functionalities of the buttons
- (reviewed) #1076 Generalize pointer scaling and color change during trigger event
- (merged) #1086 Make texture scale changeable by display DPI
- (opened) #1087 Enable YouTube double captions to fit 3D video playing
- (reviewed) #1091 Properly set the Quest3 device name
- (merged) #1094 Add break for all cases in setting device type name
- (reviewed) #1095 Remove Khronos OpenXR patch
- (reviewed) #1092 Use Khronos OpenXR headers in OCULUSVR builds
- (reviewed) #1099 Select 90Hz refresh rate for Quest3
- (closed) #1100 Always bypass cache for some specific urls
- (reviewed) #1102 Bump sharp from 0.30.5 to 0.32.6 in /tools/compressor
- (merged) #1104 Enable word auto complete for Latin keyboards
- (reviewed) #1105 Increase logical size and resolution of Web pages
- (reviewed) #1106 Revert “Increase logical size and resolution of Web pages”
- (merged) #1107 Fix widgets hovering in library UI when DPI is not 100
- (reviewed) #1108 Increase logical size and resolution of Web pages (relanded)
- (closed) #1111 Add head lock feature in hamburger menu
- (closed) #1113 Also trigger key event when we scroll by D-pad
- (merged) #1114 Fix selection menu location for web pages
- (reviewed) #1116 Desktop Mode overrides for popular Chinese websites
- (merged) #1119 Hide brightness button when playing video in Passthrough
- (reviewed) #1124 Support head lock
- (reviewed) #1085 Auto Enter WebXR
- (reviewed) #1126 Fix SnapdragonSpaces build docs
- (reviewed) #1125 Prevent windows out of reach
- (merged) #1127 Revert “Enable showing all build warning”
- (merged) #1129 Fix several issues related to “center windows vertically” and drag move in curved mode
- (merged) #1130 Add group for experimental features in display settings
- (merged) #1131 Download Keyboard dictionaries on demand
- (merged) #1132 Add dictionaries to download in props.json
- (reviewed) #1136 Different density and DPI per build
- (reviewed) #1137 Bump actions/setup-java from 3 to 4
- (reviewed) #1135 Add two new environments for 1.5.2
- (merged) #1140 Fix disk LRU cache key formatting error
- (reviewed) #1142 [ML2] Disable Hardware Acceleration for rendering UI widgets
- (reviewed) #1143 Rename environment to “Winter Night”
- (reviewed) #1139 [ML2] Add 3D controller model
- (reviewed) #1146 Set default density to 1.25
- (opened) #1147 Do not let headlock update the position of the window while resizing
- (opened) #1148 Press on the skybox to reorient
- (reviewed) #1152 Initialize the VR external context after initializing Java
- (reviewed) #1163 Extract launch parameter names to constants
- (merged) #1165 Lower the maximum display DPI to 300
- (reviewed) #1169 Fix bug when moving large windows
- (reviewed) #1170 [Pico] Rename PicoXR device type to Pico4x
- (reviewed) #1171 Open immersive experiences directly
- (reviewed) #1174 Add UA override for courses.certify-ed.com
- (merged) #1175 Environments manager code logic cleanup
- (reviewed) #1176 Bump com.android.tools:r8 from 8.2.33 to 8.2.42
- (reviewed) #1178 Clean composing text when resetting the keyboard layout
- (merged) #1185 Allow disabling Latin Keyboard input auto complete
- (merged) #1189 Fix issues related to auto complete
- (closed) #1192 Fix controllers disappear during video playback
- (opened) #1193 Reset windows position when user tries to reorient via controllers
- (merged) #1194 Improving compose text input
- (reviewed) #1195 Properly support vertical videos
- (reviewed) #1197 Fix controllers disappearing
- (reviewed) #1198 Cleanup fullscreen code
- (merged) #1200 Fix several issues when playing VR videos
- (reviewed) #1182 Add support for Pico Neo3 controllers
- (merged) #1205 Fix typing in Android widgets without auto compose
- (opened) #1207 Remove reliance of onFirstContentfulPaint
- (reviewed) #1208 Bump gradle/gradle-build-action from 2 to 3
- (reviewed) #1209 Bump androidx.fragment:fragment from 1.4.1 to 1.6.2
- (merged) #1210 Use doApply for setHeadLock and setWindowMovement
- (reviewed) #1214 Don’t go back with buttons B and Y
- (reviewed) #1217 Synthesize FCP for cached pages
- (reviewed) #1218 Update telemetry-related privacy options
- (reviewed) #1219 [ML2] Add MagicLeap2 device type to VRControllerType
- (closed) #1220 Update telemetry-related privacy options string translation
- (reviewed) #1223 Modernize deprecated getMetrics(DisplayMetrics) in Display
Issues opened/helped with
- (opened) #797 Modernize deprecated updateConfiguration(Configuration,DisplayMetrics) in Resources
- (opened) #798 Use MediaStore.Downloads to index downloads instead
- (resolved) #799 Modernize deprecated getMetrics(DisplayMetrics) in Display
- (resolved) #800 Modernize deprecated setSystemUiVisibility(int) and related flags in View
- (resolved) #801 Modernize deprecated AsyncTask
- (resolved) #802 Modernize deprecated getConnectionInfo() in WifiInfo
- (resolved) #803 Modernize deprecated CONNECTIVITY_ACTION in ConnectivityManager (and bug fix on new methods)
- (opened) #805 Modernize deprecated JobIntentService
- (resolved) #810 Remove deprecated cookieLifetime
- (resolved) #822 Modernize deprecated dispatchConfigurationChanged(Configuration)
- (resolved) #823 Upgrade the CMakeList.txt
- (resolved) #835 Missing some symbols / keys from the virtual keyboard
- (resolved) #841 Migrate from org.mozilla.components:browser-search to feature-search
- (resolved) #214 Firefox Accounts authentication breaks if you navigate to another page
- (resolved) #845 Keyboard layout doesn’t match the system’s language
- (resolved) #777 Need to format file sizes consistently
- (resolved) #653 Use a different application name for HVR mainland China package
- (addressed) #89 [OpenXR] When headset tracking is off, windows appear at “ground” level (Oculus)
- (resolved) #778 The Download Confirmation Dialog shouldn’t center the question
- (resolved) #423 Implement date/time picker
- (resolved) #654 Target Android API level 32
- (resolved) #688 Keep the selected options of HTML <select> multiple Attribute
- (resolved) #875 Dark mode support
- (resolved) #715 Remove WaveVR build dependency
- (resolved) #890 Local Gecko builds are not used by default when building a package
- (resolved) #896 DateTime picker prompt dialog is not properly triggered
- (closed) #922 Add Yandex to the list of available search engines
- (closed) #928 Missing the “Share with other apps” option in the downloads lists
- (resolved) #923 Youtube VR videos with lower quality than expected
- (resolved) #929 Search in page
- (resolved) #943 The ‘Address bar auto-complete’ feature can not be disabled
- (addressed) #939 Tabs get closed with updates
- (resolved) #949 “RESTART NOW” does not restart
- (resolved) #940 Implement the feedback form with a native UI dialog
- (resolved) #717 Youtube Captions
- (resolved) #964 False positive network status when starting Wolvic
- (resolved) #874 No playback in Apple TV streaming service
- (resolved) #712 Too much restart needed to restablish unstable connection
- (resolved) #666 Persistent setting for the passthrough mode
- (addressed) #493 Increase window parameter adjustment options in resize menu
- (addressed) #353 Download dialog cannot show repeatedly
- (addressed) #482 Empty canvas element after exiting VR
- (addressed) #662 Leak of surface when exiting VR mode
- (resolved) #545 3D SBS not working in curved mode
- (resolved) #489 [Privacy and Security] Add trusted Root CA option
- (resolved) #461 Add more options to view 3D-SBS-Videos
- (addressed) #927 Drag and rotate windows using the controller
- (resolved) #619 When running a noapi build, a black screen is displayed
- (resolved) #970 Some Web XR Links do not work in Kiosk Mode
- (addressed) #977 Restore the FxR inherited versionCode auto generation
- (resolved) #981 Opening a URL from the command line always opens a new tab
- (addressed) #976 [OpenXR] Revamp finalization of OpenXRLayer subclasses
- (resolved) #998 Date picker can be too tall
- (addressed) #86 Rendering artifacts in Atomic City scene of Mozilla Hubs
- (addressed) #225 No audio casting stream from Wolvic
- (resolved) #226 No sound effects playing Moon Rider (https://moonrider.xyz)
- (addressed) #782 Support KTX v2
- (resolved) #660 Speech input on vr keyboard
- (resolved) #171 Fragmented subtitles in 3D side-by-side movie
- (addressed) #498 Needs to start in desktop mode
- (resolved) #299 in kiosk mode, maybe it needs a loading progress bar of the webxr content
- (addressed) #87 Saving and loading don’t work in Brushworkvr app
- (addressed) #1011 Dot (.) unconditionally appended to voice search text
- (resolved) #1013 Voice input content UI overflow and not stick to the latest
- (resolved) #963 Environments download should use
getFilesDir()/getCacheDir()to store the downloaded zip file - (addressed) #598 Media stream detached from window in some cases?
- (addressed) #731
 The 360° background could be updated according the webpage
- (resolved) #345 on a shared device clearing cache and history it does not reset everything
- (resolved) #236 softlocking quest when opening dll file in external app
- (resolved) #1023 Evaluate the need for the media session extension
- (addressed) #473 Add a glTF/glb loader
- (addressed) #1029 Make the CrashReporterService work again
- (resolved) #1044 Implement an Android’s MediaPlayer AudioEngine
- (addressed) #99 Click and Drag windows
- (resolved) #1055 There is no curved window in full-screen video mode
- (resolved) #1058 华为vr glass
- (resolved) #1059 华为vrglass
- (resolved) #1062 Not installable on Quest 3
- (resolved) #1067 Enable haptic feedback when controller pointer swipes across widgets/web page
- (resolved) #1069 Allow ‘Device Name’ change in Firefox/Mozzila Sync settings.
- (addressed) #1065 can wolvic support WebGPU? and if not, what’s the roadmap?
- (resolved) #737 Request: autocorrect/text prediction
- (resolved) #1078 How to improve sharpness at 0.5 window size
- (resolved) #1093 Allow users to use the Zoom to change the size of the rendered web content
- (addressed) #1097 CORS errors on same origin inconsistent with other browsers (Same Origin Policy)
- (resolved) #544 InputMethodManager: Display ID mismatch found
- (resolved) #1088 Default values for display density and DPI
- (addressed) #1110 Spatial navigation support for AR/VR controllers with D-pads
- (opened) #1121 Investigate the feasibility of newer Mozilla Android components for sessions
- (resolved) #1128 Download keyboard auto-complete dictionaries on demand
- (resolved) #938 Zoom in and out
- (resolved) #1133 Pico 4 upload a new environment?(adb command not recognize wolvic * file/folder)
- (resolved) #1134 Request to adjust screen distance and increase resolution for pico4
- (resolved) #1164 Setting DPI too high causes thermal runaway
- (resolved) #1166 Disabling 360 background
- (resolved) #1162 wolvic support to play 360 view & Horizontal Panoramic View pictures which is photoed by the customers
- (addressed) #1183 Text added to the wrong place when autocomplete is active
- (resolved) #1181 Controllers disappear during video playback
- (resolved) #1186 Autocomplete: blank space requires tapping on the spacebar twice
- (resolved) #1187 Autocomplete: keyboard becomes sluggish when autocompleting medium-long words
- (addressed) #1211 Automatic VR 360 WebXR Open
 The 360° background could be updated according the webpage
Nuevo podcast «Accesibilidad con Tecnologías libres»
Me complace compartir con vosotros la presentación de el nuevo podcast «Accesibilidad con Tecnologías libres». Bueno en realidad no es tan nuevo, pero hasta ahora no me había podido centrar en él y no me gusta publicar cosas sin escucharlas antes. Fue presentado el 30 de septiembre de 2023 y ya lleva cuatro programas, el de presentación y tres más que iré desgranando poco a poco.
Nuevo podcast «Accesibilidad con Tecnologías libres»
Jorge Lama, Víctor , David Marzal, Thais Pusada, Pablo Arias, Jonathan Chacon y Markolino son el equipo reunido para crear el podcast Accesibilidad con Tecnologías libres, un podcast para hablar sobre temas de accesibilidad y tecnologías libres.
En palabras de sus creadores:
En informática, la accesibilidad incluye diferentes ayudas como pueden ser las tipografías de alto contraste o gran tamaño, magnificadores de pantalla, lectores y revisores de pantalla, programas de reconocimiento de voz, teclados adaptados y otros dispositivos apuntadores o de entrada de información.
Además, las inteligencias artificiales están empezando a ser un gran aliado para mejorar la accesibilidad en muchos aspectos. Existen podcasts y canales de vídeo que hablan de la accesibilidad centrándose en entornos Windows o de Apple porque son los más conocidos por el público generalista. Pero en este podcast queremos dar a conocer otros aspectos de la accesibilidad y su relación con otras tecnologías menos conocidas.
Tecnologías que consideramos libres y que nos parecen mejores para la sociedad, en muchos casos…
Aprovecho para dejaros el enlace del rss para que no os perdáis ningún episodio y también os dejo el audio del programa de presentación donde Jorge va presentando a cada uno de los co-presentadores, explicando su sección y haciendo una intro de lo que hablarán en el próximo programa.
Por supuesto, os invito a visitar la página de Archive.org donde están recogidos el resto de programas y donde nos indican también aquellos que estań subtitulados, aunque creo que al final lo estarán todos:
Créditos de la música:
La música usada ha sido «Evening» de Kevin MacLeod (incompetech.com)
Licensed under Creative Commons: By Attribution 4.0 License
http://creativecommons.org/licenses/by/4.0/
Personalmente, me parece un podcast muy interesante que aborda un tema recurrente en el mundo del Software Libre pero que todavía está lejos de solucionarse. Los diferentes proyectos de escritorio de GNU/Linux implementan cosas pero en muchas ocasiones no están coordinadas realmente con las personas que las necesitan. Esperemos que en los próximos años este aspecto se vaya mejorando y, si ocurre, creo que este podcast tendrá parte de culpa, en el buen sentido de la palabra.
Más información: Accesibilidad con Tecnologías Libres
La entrada Nuevo podcast «Accesibilidad con Tecnologías libres» se publicó primero en KDE Blog.
du | Directory Size in the Terminal
Directory Size in the Terminal | du
#openSUSE Tumbleweed revisión de la semana 7 de 2024
Tumbleweed es una distribución de GNU/Linux «Rolling Release» o de actualización contínua. Aquí puedes estar al tanto de las últimas novedades.

openSUSE Tumbleweed es la versión «rolling release» o de actualización continua de la distribución de GNU/Linux openSUSE.
Hagamos un repaso a las novedades que han llegado hasta los repositorios esta semana.
Y recuerda que puedes estar al tanto de las nuevas publicaciones de snapshots en esta web:
El anuncio original lo puedes leer en el blog de Dominique Leuenberger, publicado bajo licencia CC-by-sa, en este este enlace:
Esta semana se han publicado 5 nuevas snapshots (0209, 0211, 0212, 0213, y 0214). Lo que es la media de publicaciones semanales de actualizaciones en Tumbleweed.
Los cambios más relevantes son:
- SDL 2.30.0
- c-ares 1.26.0
- fwupd 1.9.13
- PostgreSQL 16.2
- Pulseaudio 17.0
- GTK 4.12.5
- Python 3.11.8
- KDE Frameworks 5.115.0
- RPM 4.19.1.1
- Node.JS 21.6.1
Y esta es la lista de cambios que se estñán testeando para próximas semanas:
- Meson 1.3.2
- Shadow 4.14.5
- pkgconf 2.1.1
- RPM
- Un trabajo de limpieza para eliminar python2
- dbus-broker
- libxml 2.12.x
- GCC 14
Si quieres estar a la última con software actualizado y probado utiliza openSUSE Tumbleweed la opción rolling release de la distribución de GNU/Linux openSUSE.
Mantente actualizado y ya sabes: Have a lot of fun!!
Enlaces de interés
- ¿Por qué deberías utilizar openSUSE Tumbleweed?
- zypper dup en Tumbleweed hace todo el trabajo al actualizar
- ¿Cual es el mejor comando para actualizar Tumbleweed?
- ¿Qué es el test openQA?
- http://download.opensuse.org/tumbleweed/iso/
- https://es.opensuse.org/Portal:Tumbleweed

——————————–
openSUSE Tumbleweed – Review of the weeks 2024/07
Dear Tumbleweed users and hackers,
This week we have released 5 snapshots (0209, 0211, 0212, 0213, and 0214). With 5 snapshots, this is quite a normal week.
The most relevant changes in those snapshots were:
- SDL 2.30.0
- c-ares 1.26.0 (after a lengthy staging phase)
- fwupd 1.9.13
- PostgreSQL 16.2
- Pulseaudio 17.0
- GTK 4.12.5
- Python 3.11.8
- KDE Frameworks 5.115.0
- RPM 4.19.1.1
- Node.JS 21.6.1
The list of things currently being tested remained largely unchanged:
- Meson 1.3.2
- Shadow 4.14.5
- pkgconf 2.1.1
- RPM: enable reproducible builds by default (bsc#1148824). For upstream versions see: https://github.com/rpm-software-management/rpm/pull/2880
- A bunch of cleanup work to eliminate more of python2 (boo#1219306)
- dbus-broker: a big step forward; upgrades seem to be an issue that needs to be addressed
- libxml 2.12.x: slow progress
- GCC 14: our usual 2-phase approach to introduce it. Currently working on phase 1, meaning GCC14 will be providing the base libraries (libgcc_s1, libstdc++…). The compiler itself will stay at version 13 for now. Only one issue left: qemu fails to build